
¿Quieres mejorar el contenido del nodo? Intente realizar una solicitud de edición.
In this node would look at which Machine Learning model was used during the research, even though that might sound scary or complicated, in reality it is actually not a complex method. We would concisely go over the models tested, a short node about the key methods used.
Short Intro
Section of this node - https://www.hubnx.com/nodes/200b2ec1-37ec-4be6-adc7-57838917d255/sections/c1677a39-c987-48cd-8d2f-c896a09eff0a
So, what exactly did the researchers used, as there are plenty of machine learning models that could have been implemented for this project. Some people might think of using 'Black box' type of models, assuming they would work well, even though they are hard to interpret. However, in reality the model used was pretty simple, lets see what exactly they did.
ML Models
No neural networks.
No transformers.
Just good, simple to understand linear regression.
They tested 3 models -
1. Tweet-Rate Only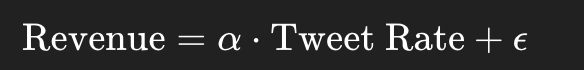
This alone gave an R² of 0.80+ - already better than many industry predictions.
R^2 ( R squared ) is a measurement used to determine the efficiency of Machine Learning model, it ranges from 0 to 1, higher number means better performance.
2. Tweet Rate + Theater Count

R² = 0.93 - almost perfect correlation.
3. Post-Release Sentiment Model
Sentiment didn’t matter before release, but it helped estimate second-weekend drops.
If a film had a strong first weekend but poor sentiment, week 2 collapsed.
This showed how volume predicts interest, and tone predicts longevity.
1
0
0
0

Comentarios