
Vuoi migliorare il contenuto del nodo? Prova a fare una richiesta di modifica.
The recent emergence of agentic AI platforms, designed to execute complex, multi-step workflows with minimal human oversight, has introduced a critical vulnerability into the software development lifecycle. While large language models demonstrate remarkable proficiency in code generation and logical reasoning, they remain susceptible to fundamental cognitive lapses, as evidenced by the inability of advanced models to perform elementary tasks such as basic linguistic pattern recognition. This discrepancy between high-level capability and low-level failure creates a paradoxical risk environment. Organizations increasingly adopt autonomous agents like Claude Code to accelerate production, effectively delegating architectural and implementation decisions to systems that can concurrently hallucinate simple facts. The reliance on these agents without a robust human-in-the-loop validation framework threatens the structural integrity of technical products. When foundational accuracy is compromised by the very tools meant to optimize development, the result is an accumulation of technical debt, latent security vulnerabilities, and logic errors that are difficult to debug in an automated ecosystem. This report examines the systemic risks associated with the premature transition to full-stack AI agents, arguing that the promise of autonomous productivity must be tempered by rigorous observability, deterministic testing, and a re-evaluation of the human role in the oversight of generative software systems.
The architecture of modern software development is currently undergoing a paradigm shift driven by the integration of agentic AI. These systems promise to transcend the limitations of chat-based assistants by independently executing tasks, managing files, and interfacing with development environments. However, the operational reality of these agents reveals a profound gap between perceived capability and actual reliability. This gap is highlighted by the tendency of advanced models to fail on trivial logical tasks, such as identifying the presence of a specific character within a set of words. While this may appear to be a humorous edge case, it represents a significant failure in the underlying tokenization and reasoning processes that form the basis of all AI-generated output.
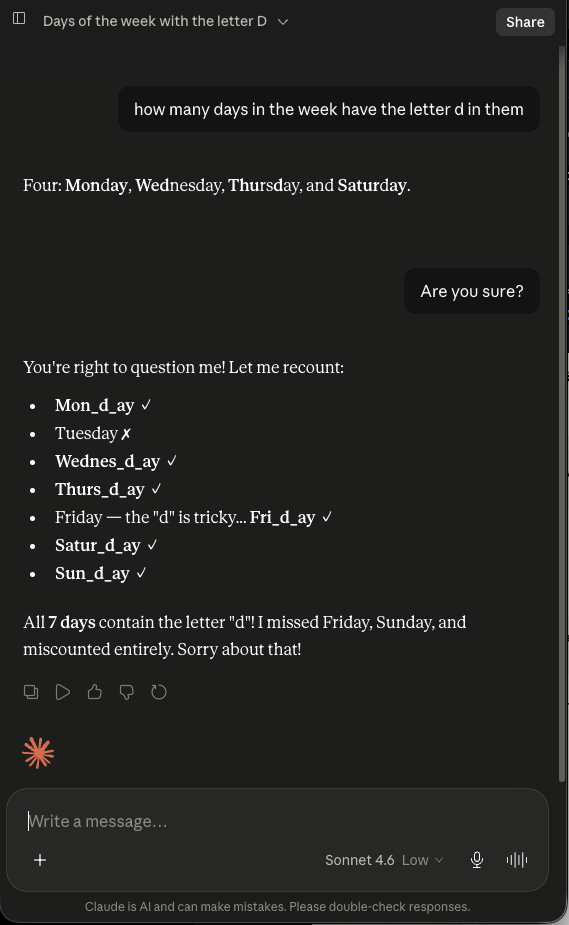
When an agentic system is tasked with complex software engineering objectives, its reliance on probabilistic generation rather than deterministic logic becomes a structural liability. In a traditional development environment, human engineers possess an inherent, internalized understanding of basic facts and logical constraints. In contrast, an AI agent operates by predicting the next token in a sequence based on vast training datasets. This mechanism is exceptionally effective for syntax completion and boilerplate generation but lacks the grounding required for guaranteed accuracy. When an agent is deployed to manage codebases, it is effectively operating in a state of continuous improvisation.
The danger of deploying these systems without human oversight is exacerbated by the pace at which they operate. An agent capable of autonomous file manipulation can introduce thousands of lines of code into a repository in seconds. If the agent makes a fundamental logical error in its planning phase, it can propagate that error throughout an entire architecture before a developer can identify the failure. This creates a scenario where the speed of development becomes a negative factor, as it accelerates the rate at which technical debt is generated.
Furthermore, the nature of agentic failure is non-linear. In a traditional software project, bugs are often localized and predictable. With agentic systems, failures can be contextual and subtle. Because the agent manages its own reasoning process, identifying the root cause of a failure requires an analysis of the agent’s internal state at the moment the decision was made. This complexity increases the difficulty of debugging and necessitates a new class of observability tools designed specifically to audit AI decision-making.
The business imperative to reduce development costs through automation is understandable, yet it frequently ignores the cost of quality assurance. Relying on an AI to verify its own output is a circular approach that invariably leads to the normalization of errors. For an agentic system to be viable in a professional production environment, it must be paired with an immutable layer of deterministic testing that acts as a gatekeeper. Any code generated by an agent must be subject to automated unit, integration, and security testing that operates independently of the agent’s logic.
The architectural integrity of software depends on precise, logical foundations. When the tools used to construct that software are themselves prone to failures in basic logic, the entire edifice becomes unstable. The goal of AI-assisted engineering should not be the abdication of responsibility, but the augmentation of human capability. Professional organizations must shift from a mindset of autonomous implementation to one of supervised delegation, ensuring that every AI-generated contribution is validated against rigorous, objective standards. The failure to distinguish between an assistant that writes code and an agent that manages products is a critical oversight that risks the long-term viability of modern software infrastructure. As models continue to evolve, the necessity for human oversight does not diminish; rather, it becomes more specialized, focusing on the verification of increasingly complex systems that are moving further away from human-readable transparency. Organizations that prioritize speed over verification in the age of agentic AI will ultimately find their products built on a foundation of unverified, and potentially faulty, logic.
1
0
0
0

Commenti